Blog
You Can't Skip the Middle. The Two Ladders of Healthcare AI.
Every healthcare AI roadmap shows one ladder, copilots at the bottom and self-improving agents at the top. There are two. One is what you build; the other is what your organization becomes, and a four-plank bridge sits between them: legibility, trusted evidence, governance, and feedback. Most teams climb the build ladder in a quarter and assume the second ladder comes free. It doesn't. This piece maps both ladders, names the plank each rung depends on, and gives you a 3-question test to find out where your pilots stand right now.
By Joey Kennedy
Every healthcare AI roadmap we see has the same picture on slide two. A ladder. Copilots at the bottom, some kind of self-improving agent at the top, and a confident arrow pointing up.
The picture is half right. There are two ladders, and they don't move together. One is what you build. The other is what your organization becomes. The mistake we watch teams make, over and over, is climbing the first ladder and assuming the second one comes along for free.
It doesn't. Between the two sits a bridge with four planks, and the planks are the part everyone wants to skip.
Two ladders, one bridge
Here is the whole model on one page. Read each ladder bottom to top.
What you build
- CopilotsA person drives. The model suggests.
- Agent pilotsThe agent runs a bounded task. A person checks it.
- Agent harnessThe runtime around the model. Tools, memory, guardrails, evals, audit.
- Specialized modelA model tuned to your workflows and your data.
What you become
- ExperimentingLots of pilots. Nobody can say which ones work.
- LegibleYou can read what an agent did and why.
- KnowledgeableYou know, with evidence, where agents perform and where they don't.
- AdaptiveYou change agents based on that evidence.
- Self-improvingThe loop runs on its own. Humans review exceptions.
The bridge between them
Legibility. Trusted evidence. Governance. Feedback.
The left ladder is a procurement decision. You can buy your way up it in a quarter. The right ladder is an operating decision. Nobody sells it, and the only way up is through the middle.
The build ladder is shorter than it looks
Copilots are cheap and low stakes, and they're where most health systems stall. A person stays in the seat, the model drafts, and the org learns almost nothing about how the model behaves when nobody's watching.
Agent pilots are the first real step. The agent runs a prior auth check or a chart review end to end, and someone spot-checks the output. Useful. Also fragile, because the pilot lives on a laptop and a Slack thread.
The agent harness is the rung that matters. It's the runtime bolted around the model: which tools it can call, what it remembers, what it's forbidden to do, how its output gets scored, and where the audit trail lands. Our χ-BENCH work found the best frontier agents complete only 28% of complex healthcare workflows on their own. The harness is what closes the gap on the other 72%.
The specialized model sits at the top, and it's the rung people reach for first. A model trained on your workflows and your policies does outperform a general one. We built ACTAVA CURA for exactly that reason. But a specialized model dropped into an organization with no harness behaves like a specialist hired into a hospital with no charting system. Brilliant, and unaccountable.
The become ladder is the one your board is asking about
When a CEO says "we want self-improving AI," she's describing a rung on the right ladder. Self-improving is an organizational state. It means the loop from outcome to evidence to change runs without a project manager pushing it.
You can't get there from experimenting. Look at the rungs in between.
Legible means a non-technical leader can open a record and see what the agent did last Tuesday, in plain language, with the inputs it used. Most pilots can't do this today.
Knowledgeable means you can state the agent's completion rate on your workflows, with your data, against a baseline you trust. A vendor demo doesn't count. Johns Hopkins made this explicit when they chose to benchmark agents before deploying them, and it's the step most organizations skip.
Adaptive means that evidence changes something. A prompt, a tool permission, a routing rule, a human review threshold. Someone owns the change, and the change is logged.
Only then does self-improving become a real target rather than a slide.
The four planks, and what happens when you skip one
Each rung on the become ladder is gated by a plank on the bridge.
Legibility gets you from experimenting to legible. Skip it and you have agents doing work nobody can explain to a compliance officer.
Trusted evidence gets you from legible to knowledgeable. Skip it and your "performance data" is a screenshot from a sales call.
Governance gets you from knowledgeable to adaptive. Skip it and every improvement is a hotfix that nobody approved and nobody can roll back.
Feedback gets you from adaptive to self-improving. Skip it and your agents stay frozen at the version you shipped, while your workflows keep moving.
Buying a specialized model while your organization is still at "experimenting" is like buying an MRI for a clinic with no scheduling system. The asset is real. The capability isn't.
Why the middle gets skipped
Three reasons, and none of them are stupid.
Vendors sell the top rung, because the top rung demos well. Boards ask for the top rung, because that's what the analyst deck showed. And the middle is unglamorous work. Evals, permission tables, audit logs, review queues. Nobody gets promoted for a really good audit log.
The middle also feels slow, which is the part we'd push back on. A harness with evals and audit built in makes every agent after the first one faster to ship, because you stop re-deciding the same governance questions per project. The middle is the one investment that compounds.
Where ACTAVA sits
We built the platform around the bridge, because the bridge is where pilots die.
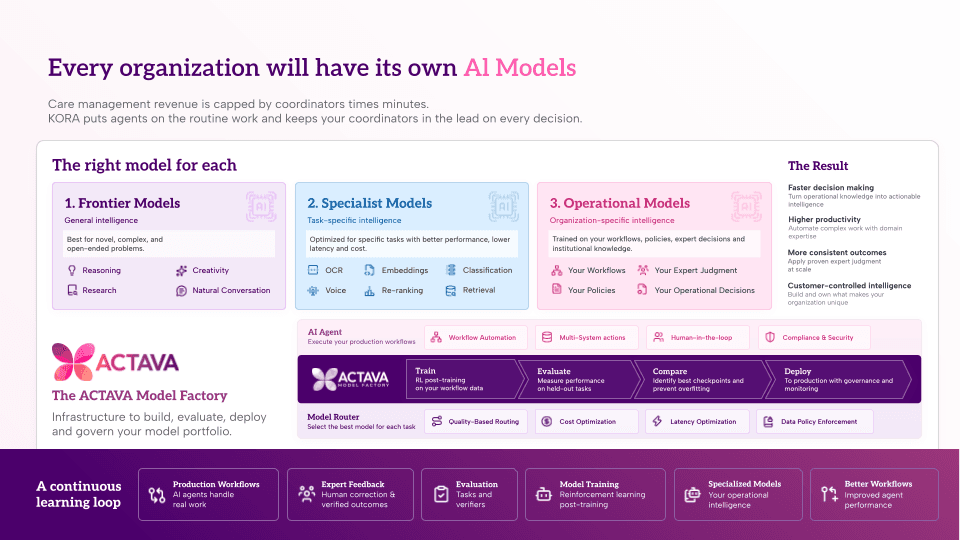
ACTAVA KORA is the harness. It covers build, test, and learn: tools, memory, guardrails, evaluation, and the record of what every agent did.
ACTAVA COMPLIANCE is the governance plank. Role-based access, human-in-the-loop thresholds, and an audit trail your compliance team can sign off on.
ACTAVA χ-BENCH is the trusted evidence plank. Real healthcare workflows, scored the same way every time, so "how good is this agent" has a number behind it.
ACTAVA CURA is the specialized model at the top of the build ladder. It earns its place because the harness underneath it can prove what it does.
A test you can run this week
Pick one live pilot. Ask three questions.
- Can you show a non-technical executive what this agent did on a specific day, and why?
- Can you state its completion rate on your workflows, measured by you?
- When it fails, what changes, who approves the change, and where is that written down?
If any answer is no, you're standing on the bridge. That's fine. Most of healthcare is standing there with you. The organizations that pull ahead over the next 2 years will be the ones that stop pretending they're already across.
Want to see the four planks running against one of your workflows?
Book a DemoSources and further reading
- χ-BENCH Update: Frontier Agents Complete Only 28% of Complex Healthcare Workflows, ACTAVA, June 2026
- 0% End-to-End: What 75 Real Workflows Say About Agent Readiness in Healthcare, ACTAVA, August 2026
- Why the Agent Harness Matters More Than the Model, ACTAVA, July 2026
- Why Johns Hopkins is benchmarking AI agents before deployment, Healthcare IT News, July 2026
- ACTAVA KORA · ACTAVA COMPLIANCE · ACTAVA χ-BENCH · ACTAVA CURA
Written by
Joey Kennedy
Chief Sales Officer
Joey joins ACTAVA with over 20 years of experience in health technology software sales and management, bringing a wealth of knowledge and a strong track record of success in the healthcare space. Joey builds winning teams and drives growth for healthcare technology across enterprise markets. Joey most recently served as SVP of Sales at Tendo, leading a team of 12 and driving $7.5 million in additional revenue in less than a year. Prior to Tendo, Joey was Chief Revenue Officer at 3 startups (two of which were in the healthcare AI space), leading to lucrative acquisitions. As an individual contributor at Vlocity (later acquired by Salesforce), Joey won the President's Cup for the top Sales Account Executive, ranked by revenue, out of 50. Joey has an MBA from UCLA with a specialization in Healthcare Marketing and a B.A. from BYU in Linguistics with a minor in Portuguese.